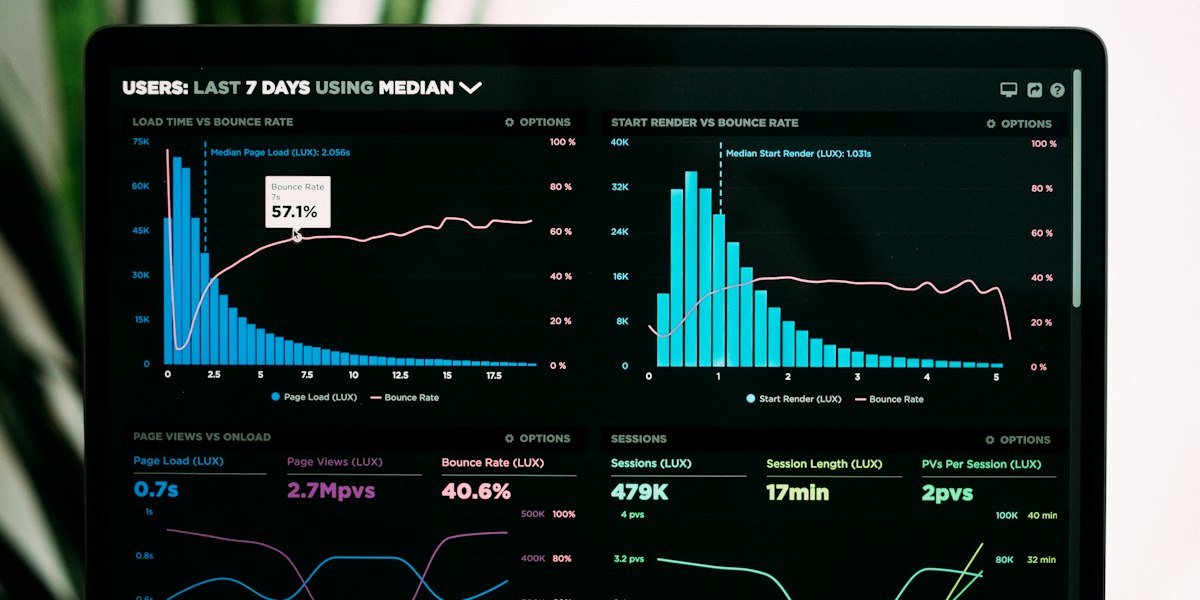
The problem observability solves
Your code works on your machine. It works in staging. Then a user reports that checkout “sometimes fails” in production, and you have no idea why — you can’t reproduce it, you can’t attach a debugger to a live server serving thousands of people, and the bug happened three hours ago.
Observability is how you answer “what is my system actually doing right now, and what did it do at 2:47pm when that error happened?” Without it, production debugging is guesswork. With it, you read the story of what happened.
Logging: the foundation
Logging is the cheapest, most universal observability tool. But most logging is done badly enough to be nearly useless.
Structured logs, not string soup
// ❌ Human-readable, machine-hostile — you can't query this
console.log('User ' + userId + ' bought ' + itemCount + ' items for $' + total);

// ✅ Structured — every field is queryable
logger.info('purchase completed', {
  userId,
  itemCount,
  total,
  currency: 'USD',
});
The difference matters enormously at scale. When you have a million log lines and need “all failed purchases over $500 in the last hour,” you can query structured logs (they’re JSON — filter by field). Unstructured strings force you to grep and regex, which falls apart fast.
A structured logger like Pino emits JSON:
import pino from 'pino';
const logger = pino();

logger.info({ userId: 42, action: 'login' }, 'user logged in');
// {"level":30,"time":1694...,"userId":42,"action":"login","msg":"user logged in"}
Your log aggregator (Datadog, Grafana Loki, CloudWatch, etc.) ingests that JSON and lets you filter, aggregate, and alert on any field.
Use log levels with discipline
Levels let you turn the volume up or down without code changes:
- error — something failed and needs attention. A human should probably look.
- warn — unexpected but handled. Worth noticing, not alarming.
- info — normal significant events: request received, order placed, job finished.
- debug — detailed diagnostic info, usually off in production.
logger.error({ err, orderId }, 'payment failed');
logger.warn({ retries }, 'retrying flaky upstream call');
logger.info({ orderId, total }, 'order placed');
logger.debug({ query, params }, 'executing db query');
Run production at info and above; flip to debug temporarily when chasing something. The discipline part: an error log should mean “a human might need to act.” If you log routine, expected things as errors, real errors drown in the noise and everyone learns to ignore the error channel — which defeats the point.
Every log needs context
A log line that says "error occurred" is worthless. You need to know which request, which user, which operation. The key tool is a correlation ID (a.k.a. request ID) attached to every log from a single request:
// Middleware assigns an ID to each request
app.use((req, res, next) => {
  req.id = crypto.randomUUID();
  req.log = logger.child({ requestId: req.id });
  next();
});

// Every log in this request now carries the same requestId
app.post('/checkout', (req, res) => {
  req.log.info({ cartId }, 'checkout started');
  // ... later, deep in some service ...
  req.log.error({ err }, 'payment declined');
});
Now when a user reports a problem, you filter logs by their request ID and see the entire story of that one request across every service it touched — in order. This single practice turns “somewhere in this haystack” into “here’s exactly what happened.”
Never log secrets
This is a security incident waiting to happen. Logs get shipped to third-party services, stored for months, and viewed by many people.
// ❌ Now the password / card / token is in your logs forever
logger.info({ user: req.body }, 'login attempt');
logger.info({ headers: req.headers }, 'incoming request'); // Authorization header!

// ✅ Log only what you need, redact the rest
logger.info({ email: req.body.email }, 'login attempt');
Configure your logger to auto-redact known sensitive fields:
const logger = pino({
  redact: ['password', 'req.headers.authorization', '*.creditCard', 'token'],
});
Assume anything you log could end up in front of someone who shouldn’t see it. Passwords, tokens, full card numbers, personal data beyond what’s necessary — keep them out.
The three pillars of observability
Logging is one of three complementary signals. Each answers a different question.
1. Logs — “what happened?”
Discrete events with detail. Best for the narrative of a specific request or error. Downside: high volume and cost at scale, and you have to know what to log in advance.
2. Metrics — “how much / how many / how fast?”
Aggregated numbers over time: requests per second, error rate, p95 latency, queue depth, memory use. Cheap to store (they’re just numbers) and perfect for dashboards and alerts.
import client from 'prom-client';

const httpDuration = new client.Histogram({
  name: 'http_request_duration_seconds',
  help: 'HTTP request duration',
  labelNames: ['method', 'route', 'status'],
});

app.use((req, res, next) => {
  const end = httpDuration.startTimer();
  res.on('finish', () => {
    end({ method: req.method, route: req.route?.path, status: res.statusCode });
  });
  next();
});
Metrics tell you that error rate spiked at 2:47pm and latency tripled. They don’t tell you why — that’s what you pivot to logs and traces for.
3. Traces — “where did the time go?”
A trace follows one request across every service and shows how long each step took. Essential in distributed systems where a slow request might be slow in any of ten services.
Request /checkout ─────────────────────────── 850ms
├─ auth check ──── 12ms
├─ load cart ───── 45ms
├─ price items ─────────── 180ms
└─ payment API ──────────────────────── 600ms  ← the culprit
That visualization instantly shows the payment API is the bottleneck. Distributed tracing tools (OpenTelemetry, Jaeger, Honeycomb) build these automatically once instrumented.
How they work together: a metric alerts you that error rate spiked → you look at logs for those errors to see what failed → you open a trace to see where in the request it broke and how long each part took. Three signals, one investigation.
Health checks and uptime
The most basic monitoring: is the service even up?
app.get('/health', async (req, res) => {
  try {
    await db.query('SELECT 1');
    res.status(200).json({ status: 'ok', uptime: process.uptime() });
  } catch (err) {
    res.status(503).json({ status: 'unhealthy' });
  }
});
Point an uptime monitor (UptimeRobot, Pingdom, or your platform’s built-in) at it. You want to hear about an outage from your monitor, not from angry users — being told your own site is down by a customer is a bad look and a slow signal.
Alerting: waking people up correctly
Alerts are how observability data reaches a human when it matters. Getting this wrong is its own failure mode.
Alert on symptoms, not causes. Alert on “error rate > 5%” or “p95 latency > 2s” — things users actually feel. Don’t alert on every internal hiccup that self-heals.
The cardinal sin is alert fatigue. If your phone buzzes 50 times a day for things that don’t matter, you’ll mute it — and miss the one that did. An alert should mean “a human needs to act now.” Everything else is a dashboard or a daily digest, not a page.
Page immediately:  site is down, error rate > 10%, payments failing
Notify (Slack):    elevated errors, slow queries, disk 80% full
Dashboard only:    request counts, cache hit rates, normal latency
Tier by genuine urgency. A good alerting setup is quiet almost all the time, and when it fires, you trust it.
Don’t over-instrument on day one
You don’t need distributed tracing for a personal blog or a small app on one server. Start with what pays off immediately:
- Structured logging with levels and request IDs — do this from the start; it’s cheap and invaluable.
- A health check + uptime monitor — five minutes of setup.
- Basic metrics (error rate, latency) once you have real traffic.
- Distributed tracing only when you have multiple services and “which service is slow?” becomes a real question.
Adding a full observability stack to a three-page app is over-engineering. Adding structured logs to anything is just good practice. Match the investment to the system’s actual complexity and stakes.
The mindset
Observability is the difference between “our site is slow, I wonder why” and “the payment API’s p95 jumped to 600ms at 2:47pm, here’s the trace, here are the error logs, here’s the deploy that caused it.” One is a shrug; the other is a fix.
Build it in as you go — structured logs with context, a health check, symptom-based alerts — and production stops being a black box you poke at nervously and becomes a system you can actually see into.